Natural Language Generation aka NLG models are designed to generate human-like text and are trained on vast datasets. They have become integral to various applications, from chatbots and virtual assistants to content generation and data summarization.
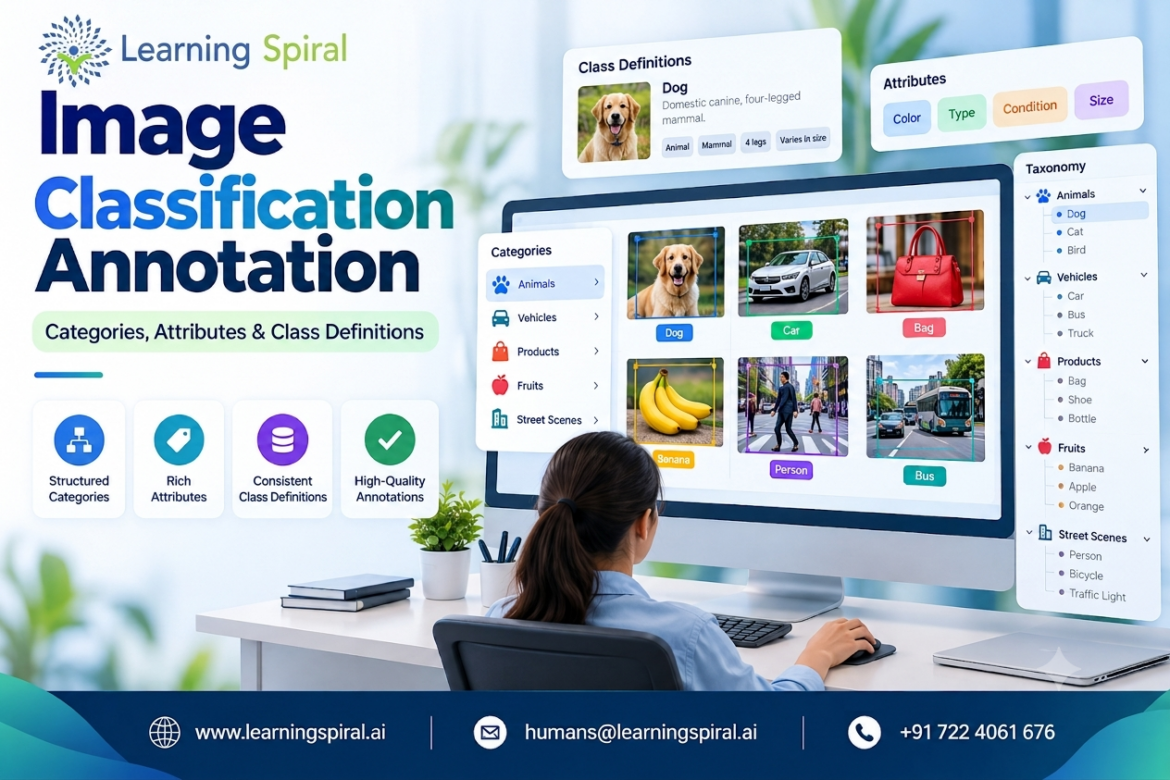
Data annotation in the context of NLG involves labeling or marking data to provide context, structure, and meaning to the training data. However, to ensure the quality and relevance of the generated content, data annotation plays a crucial role. Here’s why data annotation is important for NLG models:
- Training Data Quality: NLG models require high-quality training data to generate accurate and relevant text. Annotations help in refining the training dataset, making it more valuable for model training.
- Content Relevance: Annotated data aids NLG models in understanding the context, target audience, and the specific requirements of the generated content. This leads to more relevant and context-aware text generation.
- Customization: By annotating data that is specific to an industry, domain, or task, NLG models can be fine-tuned to generate content tailored to a particular field, such as medical, legal, or financial.
Challenges and Solutions in Data Annotation for NLG
The process of data annotation for NLG models presents several challenges, which can be addressed with the following solutions:
- Subjectivity and Ambiguity: Language is inherently subjective and often ambiguous. Annotators may have differing interpretations of the same text. Establishing clear annotation guidelines and providing annotators with examples and feedback can mitigate subjectivity and ensure consistency.
- Scalability: NLG models require large, diverse datasets for effective training. Annotating a large volume of data manually can be time-consuming and expensive. Semi-automated annotation tools and techniques, combined with crowd-sourcing, can help scale the annotation process.
- Data Quality Control: Maintaining data quality is critical. Implementing a quality control process that includes regular checks, inter-annotator agreement assessments, and feedback loops can help ensure the annotated data is accurate and reliable.
- Data Privacy and Security: If the data to be annotated contains sensitive information, anonymization techniques and strict data handling protocols must be in place to protect privacy and security.
- Adaptability: As language evolves and user preferences change, NLG models need to adapt. Continuous annotation and model retraining can help keep NLG models up-to-date and relevant.
Data annotation for NLG models is pivotal in enabling these models to generate high-quality, context-aware, and relevant human-like text. As NLG technology continues to be integrated into various applications, the role of data annotation in shaping the performance of these models will remain essential.