Every computer vision model learns from the labels it is given. If those labels are vague, overlapping or applied differently by different people, the model learns confusion instead of intelligence. That is why image classification annotation is less about clicking a label and more about designing a clear system behind it.
In this guide, we explain how to build categories, add useful attributes and write class definitions that every annotator interprets the same way. Whether you run an in-house team or work with a data annotation company, these principles decide whether your dataset becomes an asset or a liability.
What Is Image Classification Annotation?
Image classification annotation means assigning one or more predefined labels to an entire image, such as “ripe fruit”, “damaged parcel” or “helmet worn”. Unlike object detection, where you draw shapes around items, classification describes the image as a whole. According to Wikipedia’s overview of data annotation, image classification assigns predefined labels to images so that machine learning models can learn to tell them apart.
It sits at the base of the computer vision pipeline. Many projects start here before moving to bounding boxes or segmentation. If you are exploring the wider field, our image annotation services cover classification, detection, segmentation and more.
Why Category Design Matters More Than Annotation Speed
Teams often rush to start labeling and fix the taxonomy later. This is expensive. Re-labeling thousands of images because two classes overlapped can cost more than the original project.
A strong category structure gives you:
- Higher model accuracy, because classes are visually and logically distinct
- Faster annotation, because annotators spend less time debating
- Lower rework, because disagreements surface early
- Easier scaling, because new annotators learn from clear rules
How to Design Categories That Work
1. Make classes mutually exclusive. An image should clearly belong to one class (in single-label tasks). If “Road” and “Highway” overlap, annotators will split randomly.
2. Make the set collectively exhaustive. Add an “Other” or “Cannot determine” class so that unusual images do not get forced into wrong boxes. Track how often it is used, since a rising count signals a missing category.
3. Choose the right granularity. “Vehicle” may be too broad, while “2019 sedan with sunroof” is too narrow. Match detail to what the model must decide in production.
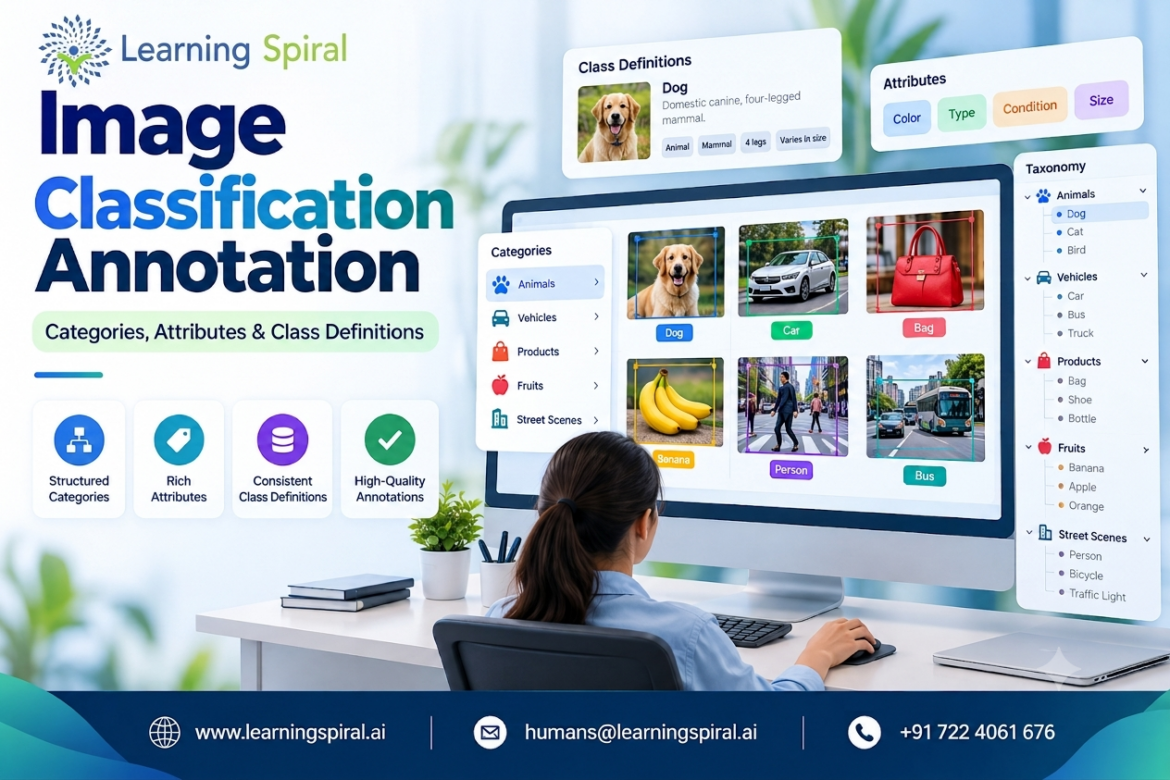
4. Use a hierarchy when needed. A parent class (Fruit) with child classes (Apple, Mango) lets you train coarse and fine models from the same labels.
5. Watch class balance. If 95% of images are “Normal”, the model will rarely learn “Defect”. Plan data collection with rare classes in mind.
Using Attributes to Add Context Without Adding Chaos
Attributes are extra properties attached to an image, such as lighting, blur, occlusion, weather or camera angle. They help you filter data, audit model failures and balance datasets.
A few rules keep attributes useful:
- Define each attribute with fixed values (for example, Lighting: Day / Night / Low light)
- Separate content attributes (what is in the image) from quality attributes (how the image looks)
- Mark which attributes are mandatory and which are optional
- Avoid creating attributes you will never use, because each one slows annotators down
Attributes become especially powerful in image annotation for autonomous vehicles, aerial imagery, agriculture, retail and logistics, where conditions change constantly.
Writing Class Definitions That Everyone Reads the Same Way
A class name alone is not a definition. “Damaged” means different things to different people. A good definition has five parts:
- Plain-language description of the class
- Inclusion rules that say what qualifies
- Exclusion rules that say what does not qualify
- Visual examples, both correct and incorrect
- Edge-case rulings, such as partially visible items, low-quality images or two classes in one frame
Add a simple decision tree for tricky classes and a tie-breaker rule (“If two classes apply, choose the one covering the larger visible area”). Version your guidelines and record every change, so you always know which rules produced which labels.
Quality Control: Keeping Labels Consistent at Scale
Even perfect guidelines drift over time. Build quality checks into the workflow:
- Gold-standard sets of pre-verified images to test annotators
- Inter-annotator agreement to measure how often people agree
- Multi-level review where a reviewer validates a sample of every batch
- Feedback loops that turn disputed images into new guideline examples
- Human-in-the-Loop (HITL) review combined with model-assisted pre-labeling
This is where an experienced data labeling company adds real value, because structured QA is built into every project rather than added at the end. See how our quality control process keeps datasets reliable.
Where Image Classification Annotation Is Used
- Agriculture: crop health, disease and ripeness grading
- Retail: product categorization and shelf compliance
- Logistics: parcel condition and package-type sorting
- Autonomous vehicles: scene, weather and road-condition tagging
- Medical annotation: scan triage and abnormality flags
- Aerial imagery: land-use and infrastructure classification
- Sports and games: scene and action tagging
- Content moderation: safe or unsafe image screening
For text-and-image workflows, explore our content classification and categorization services.
Common Mistakes to Avoid
- Launching with no written guidelines
- Creating classes that overlap
- Skipping the “Other” class
- Ignoring rare but critical classes
- Changing definitions mid-project without relabeling
- Measuring speed instead of consistency
Quick Checklist Before You Start Labeling
- Are all classes mutually exclusive and clearly named?
- Is there an “Other / Unclear” option?
- Does every class have inclusion, exclusion and examples?
- Are attributes limited to what you will actually use?
- Is there a QA plan with gold sets and agreement targets?
- Are guidelines versioned?
Why Choose Learning Spiral AI for Image Annotation Services?
Learning Spiral AI is a trusted data annotation and data labeling company in India, delivering human-in-the-loop AI data solutions across computer vision, NLP, audio and more. Our services are delivered from an ISO 27001 compliant organization by trained, in-house teams with 15+ years of experience handling sensitive data at scale.
We support image annotation, video annotation, bounding box annotation, LiDAR annotation, 3D point cloud annotation, medical data annotation, audio and text annotation, content moderation and AI training data services for robotics, autonomous systems and more. If you are comparing computer vision companies in India, we would love to prove our quality on a free pilot.
Frequently Asked Questions
Q1. What is image classification annotation?
It is the process of assigning predefined labels or categories to whole images so machine learning models can learn to recognize them.
Q2. How many classes should a classification dataset have?
There is no fixed number. Use as many as your model must distinguish in real use, and keep each class clearly separate from the others.
Q3. What is the difference between classification and object detection?
Classification labels the full image, while object detection locates and labels individual objects using shapes such as bounding boxes.
Q4. How do you measure labeling consistency?
Common methods are inter-annotator agreement, gold-standard test sets and reviewer sampling.
Q5. Can Learning Spiral AI handle custom class definitions?
Yes. We work with your taxonomy, or help you design one, and follow your guidelines throughout the project.