Dataset for Machine Learning: 7 Essential Steps to Build High-Quality AI Training Data
What separates an AI model that performs well in testing from one that delivers reliable results in the real world?
The answer often begins long before model training—with the quality of its data.
Artificial Intelligence (AI) and Machine Learning (ML) systems depend on relevant, accurately labeled and carefully validated information to recognize patterns, interpret situations and make predictions. Even sophisticated algorithms can struggle when their training datasets contain incorrect labels, incomplete examples, inconsistent formatting or significant gaps in coverage.
Building a high-quality Dataset for Machine Learning involves much more than collecting large volumes of information. It requires a structured process of data preparation, Data Annotation, Data Labeling, quality assurance and continuous improvement.
Whether you are developing computer vision systems, intelligent robots, medical AI applications or language models, understanding how to prepare machine learning datasets can improve development efficiency and support more dependable outcomes.
In this guide, we explore seven essential steps to build reliable AI training data—and how professional AI Training Data Services from Learning Spiral AI can support each stage.
What Is a Dataset for Machine Learning?
A Dataset for Machine Learning is an organized collection of information used to train, validate or evaluate machine learning models.
Depending on the application, a dataset may contain images, videos, text, audio recordings, documents, sensor measurements or three-dimensional spatial information.
For example, an autonomous driving model may require thousands of annotated road scenes showing vehicles, pedestrians, traffic signals and obstacles. A healthcare AI model may require medical images with carefully reviewed labels. A customer service chatbot may use annotated conversations to understand user intent and language patterns.
In supervised machine learning, datasets commonly contain both input information and corresponding labels that tell the model what it should learn to predict.
A properly designed dataset should reflect the intended task, include relevant real-world variation and maintain consistent labeling standards.
The development process also involves separating data into distinct subsets. The concepts of training, validation and test datasets are important because each subset serves a different purpose during model development.
A strong dataset does not simply contain more examples. It contains the right examples, structured in the right way.
Why Is High-Quality Training Data Important for AI?
Poor-quality data can limit the effectiveness of even the most advanced machine learning architecture.
Consider an AI system designed to identify damaged products in a manufacturing facility. If its training dataset contains mislabeled defects, insufficient examples of rare damage or inconsistent annotation boundaries, the model may produce unreliable predictions when deployed.
The consequences can include incorrect classifications, higher false-positive rates, missed objects, additional manual review and expensive retraining.
High-quality datasets help address these challenges by improving the consistency, relevance and usability of the information provided to machine learning algorithms.
Professional Data Annotation Services can help organizations organize complex information into structured examples that match their model requirements.
However, achieving reliable results requires quality controls across the entire dataset lifecycle—not annotation alone.
7 Essential Steps to Prepare, Annotate and Validate High-Quality AI Training Data
Step 1: Define the Machine Learning Objective
Every successful dataset starts with a clearly defined problem.
Before collecting information, organizations should identify what the AI model must recognize, predict, classify or generate.
A computer vision application may need to detect objects in images, while a natural language processing system may need to classify customer sentiment or identify named entities.
These tasks require different types of training data, annotation methods and evaluation criteria.
Project teams should establish the intended use case, expected data formats, annotation categories, performance requirements and important edge cases before beginning production.
For example, an AI system designed for warehouse robotics might need to recognize pallets, packages, workers and forklifts under changing lighting conditions.
Defining these requirements early helps prevent unnecessary data collection and reduces annotation rework.
For complex Data annotation projects, a carefully prepared project specification is the foundation of an efficient workflow.
Step 2: Collect Relevant and Diverse Data
Once the objective is established, the next step is collecting information that represents the environment in which the model will operate.
Depending on the AI application, collection sources may include cameras, microphones, connected devices, business documents, surveys, industrial sensors or specialized data acquisition systems.
Diversity is especially important.
A model trained exclusively on daytime road images may struggle with nighttime driving. Similarly, a speech recognition model trained in quiet conditions may perform poorly when exposed to background noise.
Training datasets should therefore include relevant differences in lighting, camera angles, backgrounds, environments, accents, object appearances and operating conditions.
For robotics and autonomous systems, Egocentric Data Collection and Physical AI Data Collection can help capture real-world human interactions, object manipulation and environmental changes.
Organizations should also verify the appropriate permissions and usage rights for collected information and consider privacy requirements from the beginning.
The goal is not to collect every possible example. It is to capture sufficient, representative information for the intended machine learning application.
Step 3: Clean, Organize and Preprocess Raw Data
Raw information is rarely ready for immediate model training.
Collected datasets may contain duplicate files, corrupted images, incomplete records, inconsistent formats, irrelevant samples or inaccurate metadata.
These problems can reduce training efficiency and introduce unnecessary noise.
Effective preprocessing begins by identifying unusable information, standardizing supported formats and checking that important metadata is complete.
For image datasets, preprocessing may include verifying dimensions, formats and image readability. Text datasets may require encoding normalization and document structure checks. Audio datasets may require sampling-rate verification and detection of unusable recordings.
The broader process of data cleansing helps improve the consistency and reliability of information before it enters downstream workflows.
However, cleaning should preserve meaningful variation. Removing every difficult or unusual example can leave the model unprepared for real-world conditions.
This stage is particularly valuable for large-scale Data Labeling and annotation workflows, where early preprocessing can reduce avoidable errors and wasted effort.
Step 4: Choose the Right Data Annotation Technique
Annotation converts raw information into structured examples that machine learning models can use.
The correct technique depends on the model’s intended task, the data type and the required level of detail.
Image Annotation and Image Labeling
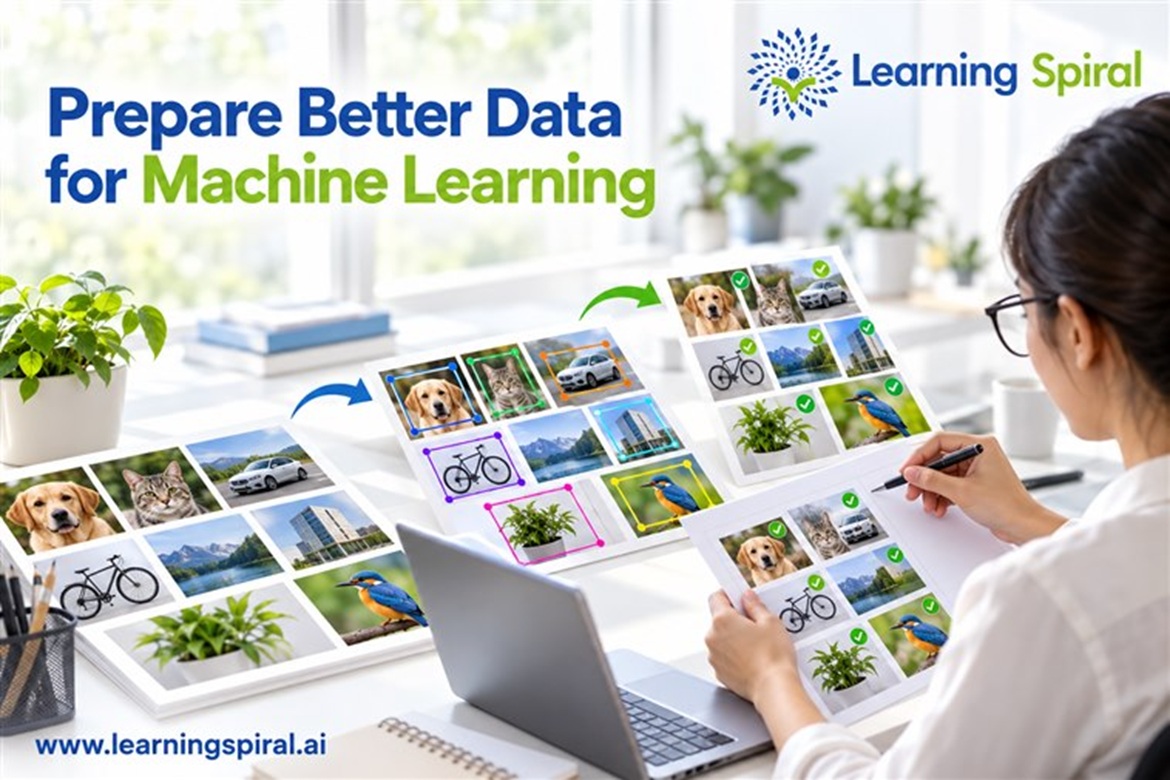
Image Annotation allows computer vision systems to identify and interpret visual information.
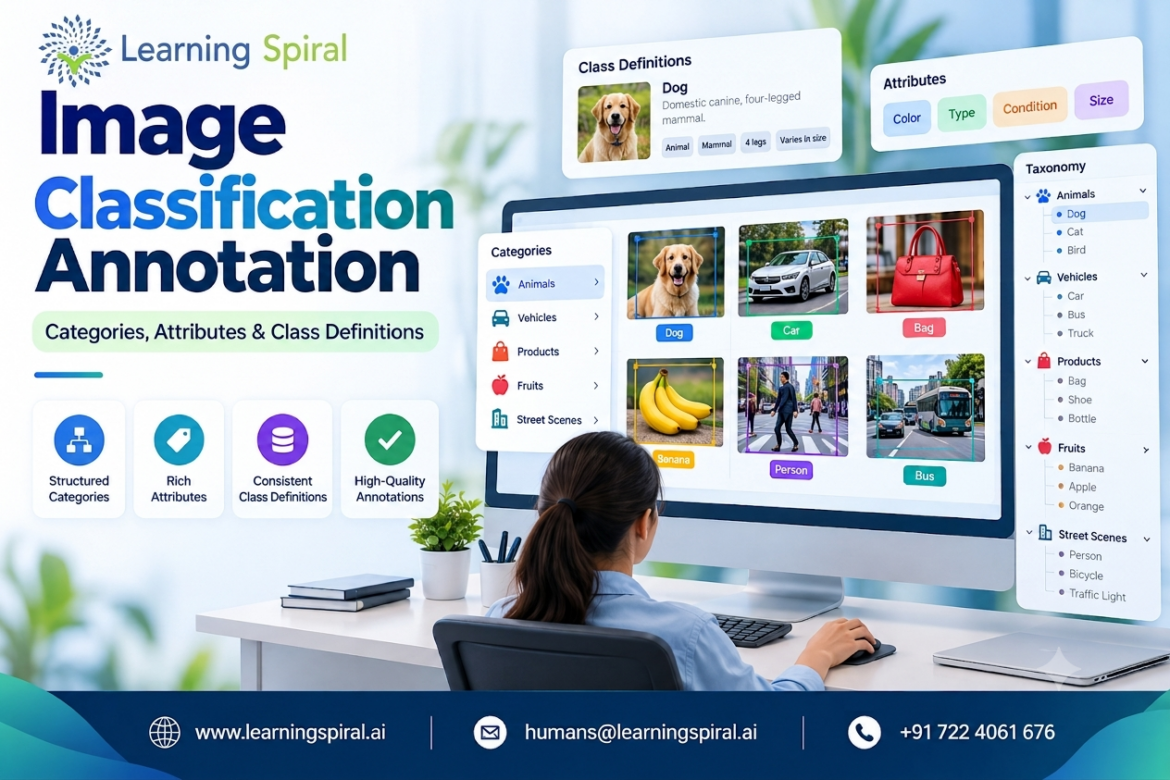
Common techniques include image classification, Bounding Box Annotation, polygon annotation, semantic segmentation, instance segmentation and keypoint labeling.
For example, Image annotation for agriculture may identify crops, weeds and damaged leaves. Image annotation for retail may categorize products or identify shelf conditions.
Similarly, Image annotation for logistics can support parcel detection, warehouse automation and inventory-related computer vision applications.
For organizations developing object detection systems, selecting the appropriate annotation technique is essential. Learn more about Image Annotation Services and how consistent class definitions support reliable labeling.
Video Annotation for Object Tracking
Video Annotation provides information about objects and activities across sequences of frames.
It supports object tracking, action recognition, movement analysis and temporal event labeling.
Applications include traffic monitoring, warehouse automation, sports analytics and autonomous vehicles.
In Image annotation for sports and games and related video labeling tasks, consistent object identities and accurate motion tracking can help machine learning models interpret player movement and game events.
Text Annotation for Natural Language Processing
Text Annotation helps AI systems understand language through structured labels and contextual information.
Typical tasks include named entity recognition, intent classification, topic categorization, Sentiment Analysis and relationship extraction.
These annotations can support search engines, customer support automation, document intelligence and language-based applications.
Audio Annotation for Speech and Sound Recognition
Audio Annotation transforms recorded sound into labeled information for speech and audio-related AI applications.
Tasks may involve transcription, speaker identification, speaker diarization, acoustic event classification and time-aligned speech labeling.
Accurate Audio data annotation is useful when developing voice assistants, speech analytics platforms and sound recognition systems.
LiDAR Annotation and 3D Point Cloud Annotation
Physical AI applications often require an understanding of three-dimensional environments.
Lidar Annotation and 3D point cloud annotation help structure spatial information captured by depth sensors.
Techniques such as 3D cuboids, semantic segmentation and object classification can support robotics, autonomous driving, infrastructure mapping and intelligent navigation.
Explore the role of Lidar Annotation in helping AI systems understand their surroundings.
Choosing the correct annotation method ensures that the dataset captures the information the model actually needs.
Step 5: Establish Clear Annotation Guidelines
Consistency is a defining characteristic of high-quality machine learning datasets.
If two annotators interpret the same object differently, conflicting labels may enter the training data.
Clear annotation guidelines help reduce these inconsistencies.
A strong guideline document should explain class definitions, annotation boundaries, inclusion and exclusion rules, labeling examples, handling of occluded objects and procedures for ambiguous cases.
For instance, a pedestrian detection project should define whether partially visible people should be labeled, how overlapping objects should be handled and what to do when an object cannot be confidently identified.
Guidelines should also be updated when new edge cases are discovered.
A professional Data Annotation Company should establish feedback channels between annotators, quality reviewers and project managers to support consistent decisions.
Well-documented standards are particularly important when Data Labeling Services involve multiple annotators, specialized domains or large project volumes.
Step 6: Validate Annotation Quality With Human-in-the-Loop Review
Even carefully designed labeling workflows can introduce errors.
Some annotations may be incomplete, while others may contain incorrect categories, inconsistent boundaries or missing objects.
This is why quality validation must be part of the production process.
A structured quality assurance workflow can combine automated checks, independent reviewer sampling, gold-standard datasets and expert adjudication.
Human in the Loop (HITL) workflows are especially valuable when automated annotations need human verification.
For example, an AI-assisted labeling system may detect vehicles in an image but miss a partially obscured cyclist. A trained reviewer can identify the missing object, correct the annotation and provide feedback to improve future work.
Organizations can measure annotation quality using metrics such as label accuracy, inter-annotator agreement, rejection rates and the frequency of recurring errors.
However, no single metric captures every aspect of dataset quality. Evaluation methods should match the task and associated risks.
For more guidance, explore Data Annotation Services and quality assurance practices for machine learning projects.
Regular quality reviews can help organizations identify problems before they affect large portions of their datasets.
Step 7: Split, Test and Continuously Improve the Dataset
The final step is preparing the dataset for model development and evaluating whether it supports reliable performance.
Machine learning data is commonly divided into training, validation and testing subsets.
The training subset helps the model learn patterns. Validation data supports model selection and tuning, while the test set provides a separate assessment of performance.
A frequently used starting allocation is 70% training, 15% validation and 15% testing, although the most appropriate split depends on dataset size, task complexity and experimental design.
Avoiding data leakage is critical. For example, highly similar frames from the same video should not be distributed carelessly across training and test subsets because this can produce misleading performance estimates.
Dataset teams should also evaluate class balance, rare events, annotation consistency and coverage of important operating conditions.
After model evaluation, error analysis can reveal where additional examples or revised labels are required.
A continuous feedback process turns dataset preparation into an iterative improvement cycle rather than a one-time task.
Common Mistakes to Avoid When Building a Machine Learning Dataset
One common mistake is prioritizing dataset quantity over usefulness. Large collections with inconsistent labels or repeated examples do not necessarily improve model performance.
Another challenge is class imbalance. If an object detection dataset contains thousands of cars but only a few examples of cyclists, the model may struggle to recognize the underrepresented category.
Incomplete annotation instructions can also create inconsistencies between team members.
In addition, organizations sometimes overlook difficult scenarios, rare objects, unusual lighting or noisy environments during data collection.
Ignoring privacy, access controls or dataset versioning can create operational and compliance risks.
Finally, failing to maintain separate evaluation data can lead to misleading results.
Addressing these issues early helps establish reliable AI Training Data Services workflows and reduces unnecessary corrections during later development stages.
How High-Quality Datasets Support Different Industries
The requirements of a machine learning dataset vary significantly across industries.
In autonomous vehicles, annotated road images, video sequences and LiDAR point clouds help systems identify traffic participants, lanes, signs and surrounding obstacles.
In healthcare, Medical data annotation can support the development of medical imaging and diagnostic-assistance applications. Such work requires suitable domain expertise, careful validation and appropriate data safeguards.
In agriculture, annotated aerial and ground-level imagery can support crop monitoring, plant disease detection and precision agriculture applications.
In retail and e-commerce, datasets may support product recognition, visual search, inventory analysis and shelf monitoring.
In logistics and manufacturing, image and video datasets can help train systems for package identification, defect detection, warehouse monitoring and industrial automation.
In robotics, Image Annotation for Robotics, depth-based labeling and real-world interaction datasets help machine learning systems recognize objects and understand their operating environments.
For language-based AI and LLM applications, carefully curated text datasets, classification labels, preference data and human evaluations can contribute to specialized model development.
Across these use cases, the connection is clear: reliable AI systems depend on data that reflects real tasks and real operating environments.
How to Choose the Right Data Annotation Company
Selecting a suitable annotation partner requires more than comparing pricing.
Organizations should evaluate the provider’s expertise in the relevant data modality, familiarity with industry-specific requirements, quality-control process, security practices and ability to scale production.
Experience with custom taxonomies, specialized annotation tools and complex edge cases is also valuable.
When evaluating Data Labeling Companies in India or Image Annotation Companies in India, ask how annotation instructions are developed, how disagreements are resolved, how quality is measured and how datasets are delivered.
A capable Data Labeling Company should be able to explain its workflow clearly and adapt annotation processes to the specific needs of a machine learning project.
The right partner should support data quality throughout the project lifecycle rather than focusing only on labeling volume.
Why Choose Learning Spiral AI for AI Training Data Services?
At Learning Spiral AI, we understand that successful machine learning projects require carefully prepared, consistently labeled and thoroughly reviewed datasets.
As a provider of Data labeling & annotation services, we support organizations developing computer vision applications, natural language processing solutions, autonomous systems and other advanced AI technologies.
Our service capabilities include Image Annotation Services, Video Annotation, Audio Annotation, Text Annotation, Bounding Box Annotation, semantic segmentation, Lidar Annotation, 3D point cloud annotation, Medical Annotation and Human in the Loop (HITL) quality review.
We also support specialized Data annotation projects involving robotics, agricultural imagery, logistics, retail, autonomous vehicles and other application-specific datasets.
By combining trained annotation teams, clearly defined project workflows and structured quality assurance, Learning Spiral AI helps organizations transform raw information into organized, model-ready training data.
Whether you are creating a new dataset or improving an existing annotation pipeline, our team can help you plan a workflow suited to your project requirements.
Conclusion: Better AI Begins With Better Training Data
Building an effective Dataset for Machine Learning requires thoughtful planning, representative data collection, careful preprocessing, appropriate annotation techniques and rigorous validation.
Each stage contributes to the reliability and usability of the final dataset.
From object detection and language understanding to autonomous vehicles and intelligent robots, high-quality training data helps provide the foundation for meaningful machine learning development.
Working with an experienced Data Annotation Company can help simplify complex labeling workflows, strengthen quality control and support scalable dataset preparation.
Frequently Asked Questions (FAQs)
1. What is a dataset for machine learning?
A dataset for machine learning is a structured collection of information used to train, validate or test an AI model. It may include images, text, audio, video or sensor data, depending on the application.
2. How do you prepare a dataset for machine learning?
Start by defining the model’s objective, collecting relevant data, cleaning and organizing the information, selecting appropriate annotation techniques, validating labels and preparing separate training, validation and testing subsets.
3. Why is data annotation important for machine learning?
Data annotation provides structured labels and contextual information that help supervised machine learning models identify relationships, recognize objects and learn from examples.
4. What is the difference between data labeling and data annotation?
Data labeling often refers to assigning categories or tags, while data annotation may involve more detailed information such as bounding boxes, polygons, segmentation masks, entity relationships or timestamps. The terms frequently overlap.
5. How can you improve dataset annotation quality?
Quality can be improved through clear labeling guidelines, trained annotators, gold-standard examples, automated validation, reviewer sampling, inter-annotator agreement checks and Human-in-the-Loop verification.
6. Which industries benefit from professional data annotation services?
Automotive, healthcare, agriculture, manufacturing, logistics, retail, robotics, sports analytics and natural language processing applications can all benefit from specialized data annotation workflows.
7. Does Learning Spiral AI provide custom dataset annotation services?
Yes. Learning Spiral AI supports customized data annotation and labeling workflows across multiple modalities, including images, video, text, audio and 3D point clouds. Project scope and quality requirements can be tailored to the intended machine learning application.